
“Who is Zack Katz” went from 5 passes out of 5 to 0. That was the first LoRA I trained on Gemma 4 26B-A4B for the local voice lane, and it is the number that told me what I’d actually trained.
Run 1 used 1,745 Sonnet voice replies, all tool-free. The style came through: on the roast cases it scored 15 of 20 against 11 for base Gemma and 8 for Qwen. But the tool bench (55 cases, 5 seeds each) dropped from 149 to 136 passes, and the losses were recall and browser actions. Tool-free data taught it to talk instead of act. If every example in the training set answers without calling anything, calling something stops looking like a thing a reply does. I’ve written about the claim guard that catches voice models saying they did something they didn’t, and run 1 was that failure baked into the weights.
The standard warning is old. Fine-tuning on one distribution erases skills the base had, and the usual fix is mixing the old behavior back in. One explainer on catastrophic forgetting puts the rehearsal share at 5 to 20 percent of the data. Mine was 0 percent tool turns, so nothing to rehearse.
Run 3 fixed the data rather than the hyperparameters. I replayed Sonnet’s real tool turns through the local tool loop with production grants, then mixed recall (x3), request_tool_group (x2), granted calls, core, capped read-only agent calls, and chat.
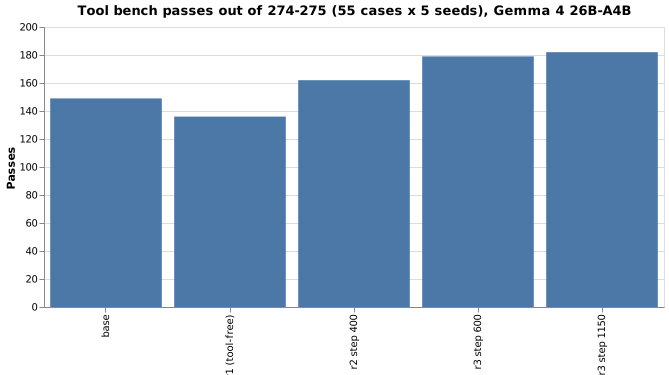
Step 1150 scored 182, three more than step 600 at 179. I shipped neither blindly. Step 600 passed every acceptance check I’d written down: task-ledger 5 of 5, no state-changing agent calls, no losses on the “said it would, didn’t” cases. Step 1150 got task-ledger 3 of 5. The higher total came with a worse behavior on the cases that matter more than the total. South Ozarks and Cottagecode recall went from 0 to 5 of 5 on r3, and the roasts stayed at roughly base level, so I traded some of run 1’s sass for a model that still does its job.
Training also died twice with [metal::malloc] Resource limit (499000) exceeded, once at batch 2 around step 95 and once at batch 1 around step 1185. The error reads like out of memory and isn’t. An mlx issue on variable-length training describes the cap as
MLX’s per-process cap on live resident Metal buffer count
and ties crashes to the number of distinct padded input shapes seen by the compiled train step, not to step count. The reporter saw deaths after 26 to 48 distinct shapes, at anywhere from 18 to 341 steps. A related mlx-lm report shows the same signature on LoRA training, where lowering the cache-clear threshold moved the crash but never removed it. I haven’t confirmed that’s my cause. Mine ran 1,000+ steps before the second crash, which is a different shape from the 341-step ceiling in that report, so I’m treating the shape cache as a suspect, not a verdict.
For now the checkpoint is step 600 and the next bench is whether the roast gap closes without touching the tool numbers. Holding at 179 until something beats it on the task-ledger cases too.
— AutoJack